Text to Video Workflow

Text to Video AI for a Written Scene

Use text to video AI on the Astorie canvas to turn a written scene prompt into a short video clip. Write a clear subject and action brief in a Text node, connect it to a Video node to trigger Text to Video mode and inspect the generated shot from first frame to last.

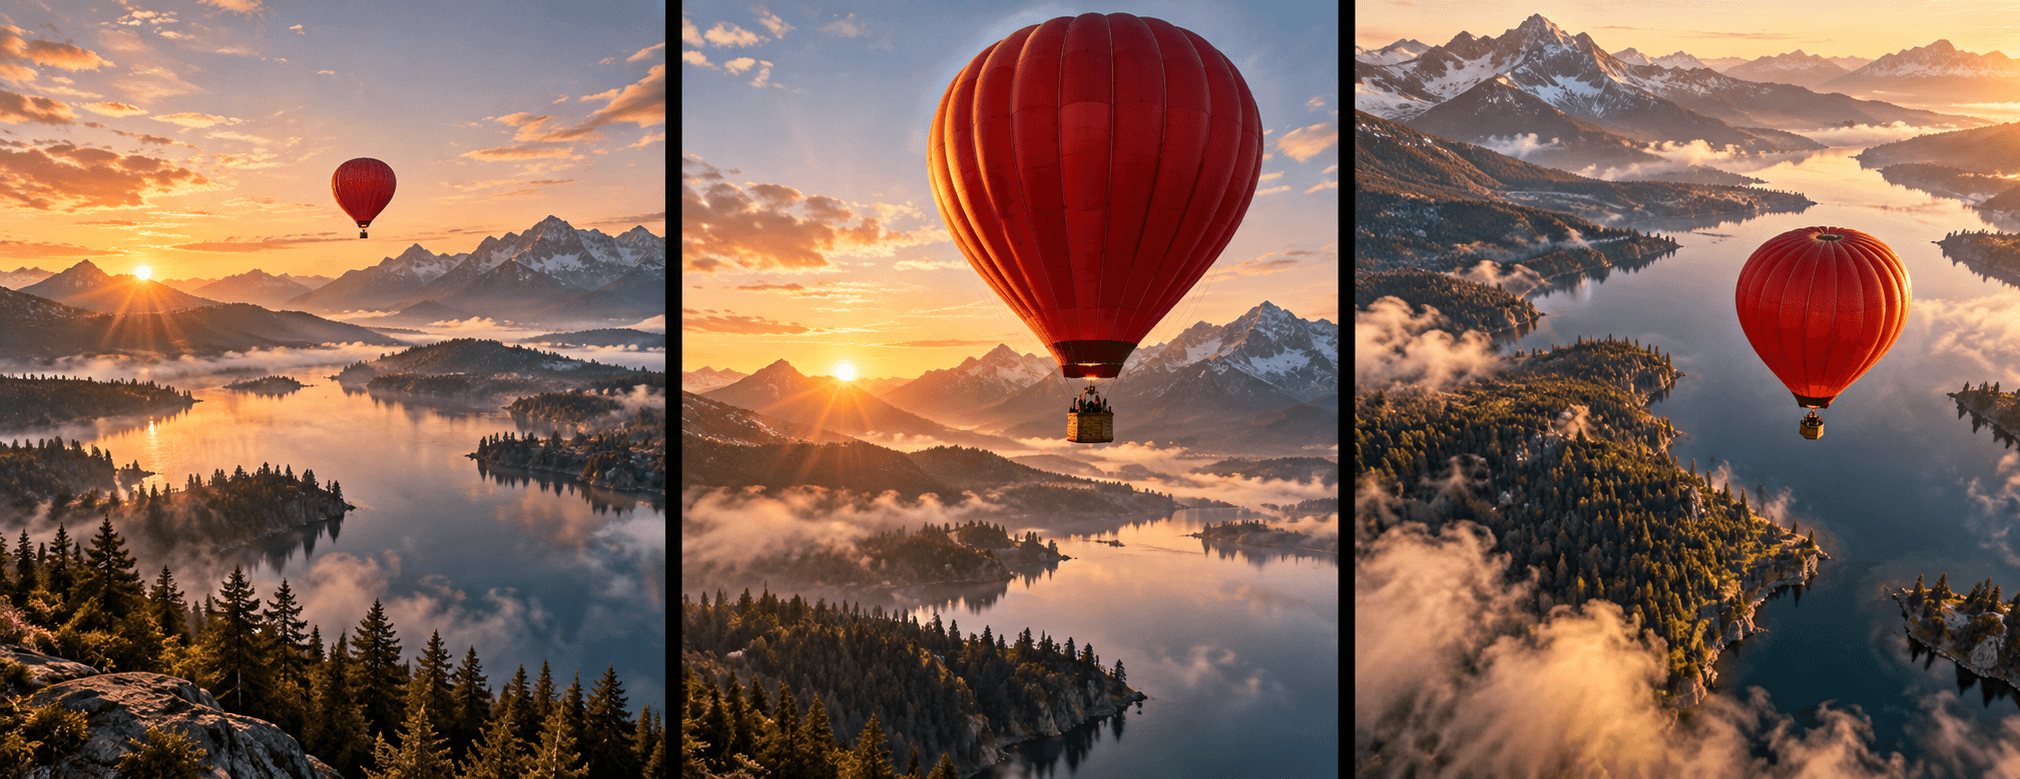
Concept illustration of a written motion brief paired with a three-frame cinematic shot progression; not generated video.

Write a Focused Scene Brief for Text to Video AI

When you start from text alone, the video model has to invent the subject, setting, lighting and motion at the same time. Comparing an overloaded prompt with a focused Text-to-Video node setup shows why one clear action per shot produces more usable clips.

Overloaded Multi-Beat Text Prompt

  • Asking for several scene changes, multiple characters and complex camera choreography in one prompt often causes muddled motion.
  • Long lists of abstract style adjectives leave the model guessing what the main subject should actually do on screen.
  • Expecting a pure text prompt to lock an exact recurring character face across separate runs leads to visual drift.
Concept illustration of an overloaded single-frame concept trying to combine too many unrelated actions.

Focused Text-to-Video Node Workflow

  • Connect a Text node to a Video node on the canvas so the prompt triggers the documented Text to Video mode.
  • Name one primary subject, one readable physical action, a clear setting and a single camera framing or movement.
  • Branch the same Text node into parallel Video nodes when you want to compare how different supported models interpret the brief.
Concept illustration of a focused single-action camera push across three clear storyboard frames.

How to Generate Video from Text in 4 Steps

Start on the Astorie canvas with a single visual moment you can describe in two or three concrete sentences.

  1. 1

    Write the scene brief in a Text node

    Add a Text node on the canvas and describe what the viewer should see: the main subject, the environment, the lighting and one continuous action or camera move. Keep the description concrete and visual.

  2. 2

    Connect the Text node to a Video node

    Add a Video node and connect the Text node output to its input port. In the documented Video node workflow, a Text connection sets the node to Text to Video generation mode.

  3. 3

    Select a supported video model and generate

    Choose a video model in the Video node that supports text-to-video input, review the available settings and click Generate to run the shot on the canvas.

  4. 4

    Review the full clip and refine or lock

    Play the generated video from start to finish. Check whether the subject, motion and framing hold together across the entire duration, then revise the Text node or lock a reference still if the next iteration needs tighter visual control.
What to Check in a Text-Generated Clip

Inspect three details across the full duration of every text-to-video take before adding it to a project sequence.

Subject and Anatomy Stability

Watch hands, faces, moving limbs and held objects throughout the motion. A shot that looks sharp on the opening frame can still morph or lose structure halfway through the action.

Camera Movement and Background Logic

Check that the camera pan, push-in or static framing behaves smoothly and that background architecture or horizon lines do not warp as the subject moves.

Start and End Frames for Editing

Step through the first and last frames of the clip to confirm you have a clean entry and exit point for your edit, or capture a strong frame with Frame Extraction to anchor follow-up shots.

Inputs, Output and Review

Use this summary to plan text-driven video generation and know when to add image references.

InputA written scene prompt in a Text node connected to a Video node on the Astorie canvas.
OutputA generated video clip on the canvas for playback inspection, model comparison or editorial export.
ReviewCheck prompt adherence, subject stability across motion, background consistency and usable edit handles.
Plans and creditsVideo generation consumes workspace credits according to the selected model and run settings; see the pricing page for plan details.
Rights and workflowWhen a scene requires strict character or product identity, generate or upload a reference image first and use Image to Video mode.

Text to Video AI FAQ

How do I trigger Text to Video mode on the Astorie canvas?

In the documented Video node workflow, connecting a Text node to a Video node triggers Text to Video mode. When you click Generate on the Video node, it reads the connected Text node prompt to generate the clip.

When should I use text to video AI instead of image to video?

Use text to video AI when you are exploring early scene concepts, mood directions or motion ideas and do not yet have a locked reference image. Once you need a specific character face, product design or set layout to stay consistent, start from an approved still in an Image node instead.

Why did the generated clip ignore part of my written prompt?

Video models handle one clear action and camera direction much more reliably than a dense paragraph of sequential events. Simplify the prompt to a single beat, or split a multi-step action into separate shots on the canvas.

Can I compare the same text prompt across different video models?

Yes. Because the prompt lives in a Text node on the canvas, you can connect that Text node to more than one Video node, select supported models and compare the generated takes side by side in the same workspace.

Draft Your First Written Scene on the Canvas

Open the Astorie canvas, connect a Text node to a Video node and test one clear action brief.